Amazon Bedrock AgentCore Automates PowerPoint Generation
A new architectural guide published on the AWS Machine Learning Blog demonstrates how organizations can leverage Amazon Bedrock AgentCore to automate the tedious process of building client presentations from complex enterprise reports.
 Radwan AbdulhadiEditor and technology writer
Automating Presentation Workflows with AI Agents
Financial services teams and other enterprise divisions often spend significant amounts of time manually transforming quarterly reports, compliance files, and market analyses into client-facing PowerPoint slides. A recently detailed implementation on the AWS Machine Learning Blog showcases an automated approach that handles reading hundreds of pages, extracting data, structuring layouts, and generating visuals in under 90 seconds during internal testing.
The underlying system relies on the newly highlighted capabilities of Amazon Bedrock AgentCore to orchestrate a supervisor agent. By using the Strands Agents framework, the supervisor intelligently routes user requests between dedicated document generation and content summarization tools.
Core Architecture and Enterprise Integration
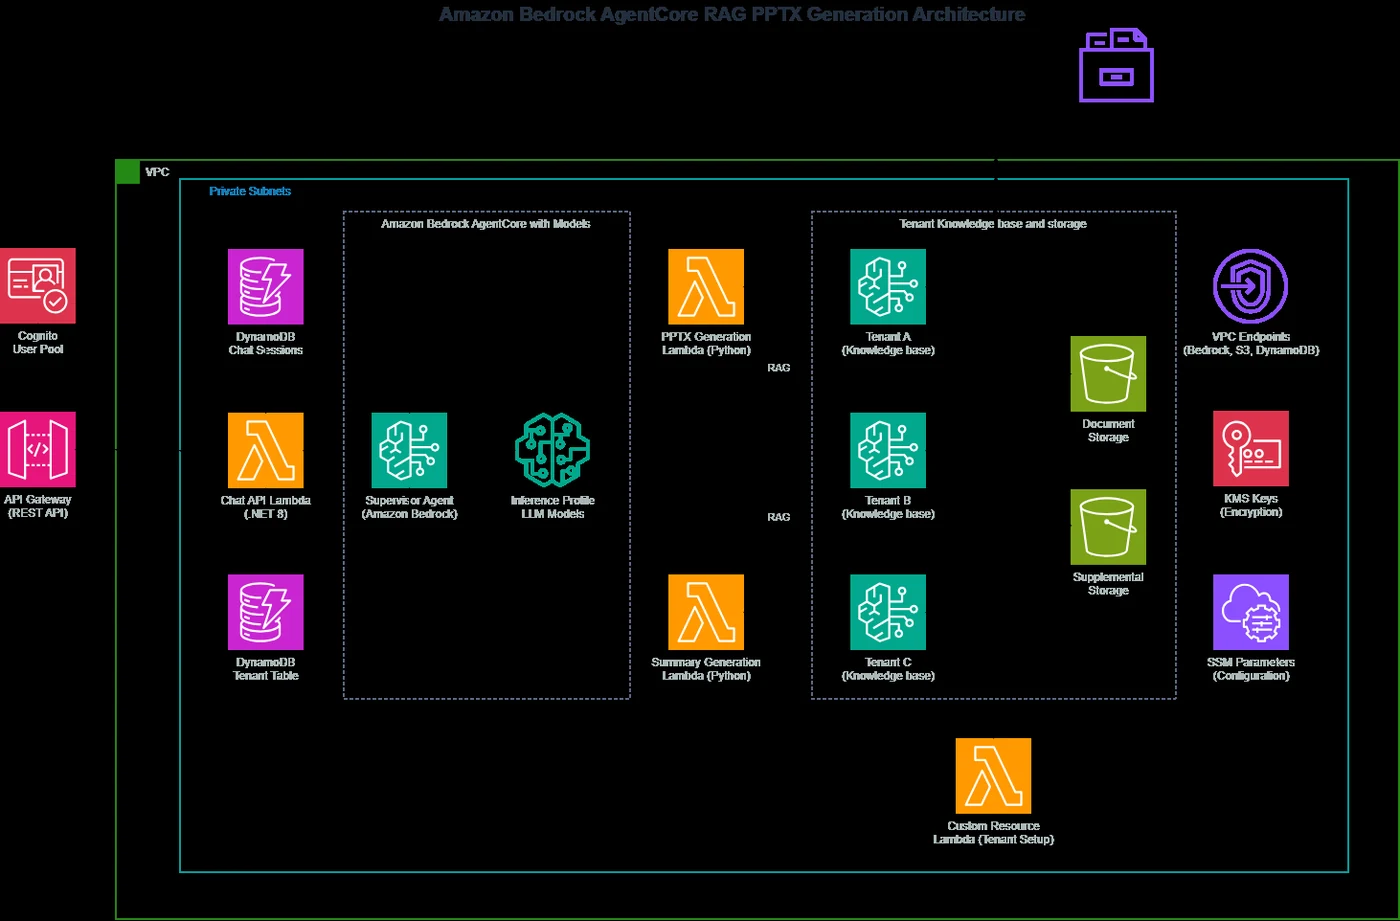
The entire solution is built around a robust, scalable architecture that can integrate seamlessly with existing corporate infrastructure. A REST API created using .NET 8 minimal APIs allows standard HTTP calls to communicate with the system, while AWS Lambda manages containerized serverless compute functions required for PowerPoint compilation.
Security remains a paramount consideration for enterprise deployments. The architecture protects sensitive workloads by employing Amazon Virtual Private Cloud (Amazon VPC) isolation, AWS Key Management Service (AWS KMS) encryption, and strict least-privilege access rules handled through AWS Identity and Access Management (IAM).
Retrieval-Augmented Generation for Accurate Content
To ensure that generated slides reflect up-to-date and factual corporate data rather than relying strictly on the underlying large language model's training parameters, the system implements a powerful Retrieval-Augmented Generation pipeline. Source documents are originally stored in Amazon Simple Storage Service (Amazon S3) before being parsed, chunked, and converted into high-dimensional vectors.
These transformations are managed via Amazon Bedrock Knowledge Bases and Amazon Titan Text Embeddings v2, while semantic vector searches are executed through Amazon OpenSearch Serverless. When a user submits a query, the system retrieves relevant document chunks and supplies them as context to Anthropic Claude Sonnet 4.6 running on Amazon Bedrock to formulate grounded responses.
Content Safety and Governance Guardrails
Enterprise environments require strict adherence to organizational compliance standards and robust data safety measures. To satisfy these needs, the workflow incorporates native content filtering and safety checks directly into the generation pipeline.
By implementing Amazon Bedrock Guardrails, the application successfully monitors both incoming user prompts and outgoing model responses. The security layer actively detects, anonymizes, or blocks personally identifiable information and prevents prompt injection risks, maintaining consistent compliance across all automated outputs.
Sources
- AWS Machine Learning BlogGenerate presentations with Amazon Bedrock AgentCore
Continue chronologically
Related entity coverage
Related stories
Amazon Bedrock Adds Anthropic In-Region Inference in Seoul and Singapore
Amazon Bedrock now supports Anthropic models with in-region inference in Seoul and Singapore for strict local data processing requirements.
AWS Recaps September 2026 AI Updates for Bedrock and Strands
Explore the September 2026 updates for Amazon Bedrock, AgentCore, and Strands, bringing broader model choice, automated syncing, and serverless agents.
Amazon Bedrock brings Claude models to India for local data processing
Amazon Bedrock expands Anthropic's Claude model availability to India using geographic cross-Region inference, keeping data processing local.
Build Multi-Agent Pipelines with Amazon Bedrock AgentCore
Learn how to build a multi-agent music production pipeline on Amazon Bedrock AgentCore Runtime Instances using shared sessions and GPU infrastructure.