Jailbroken PS5 Runs Local AI Models Past 100 Tokens
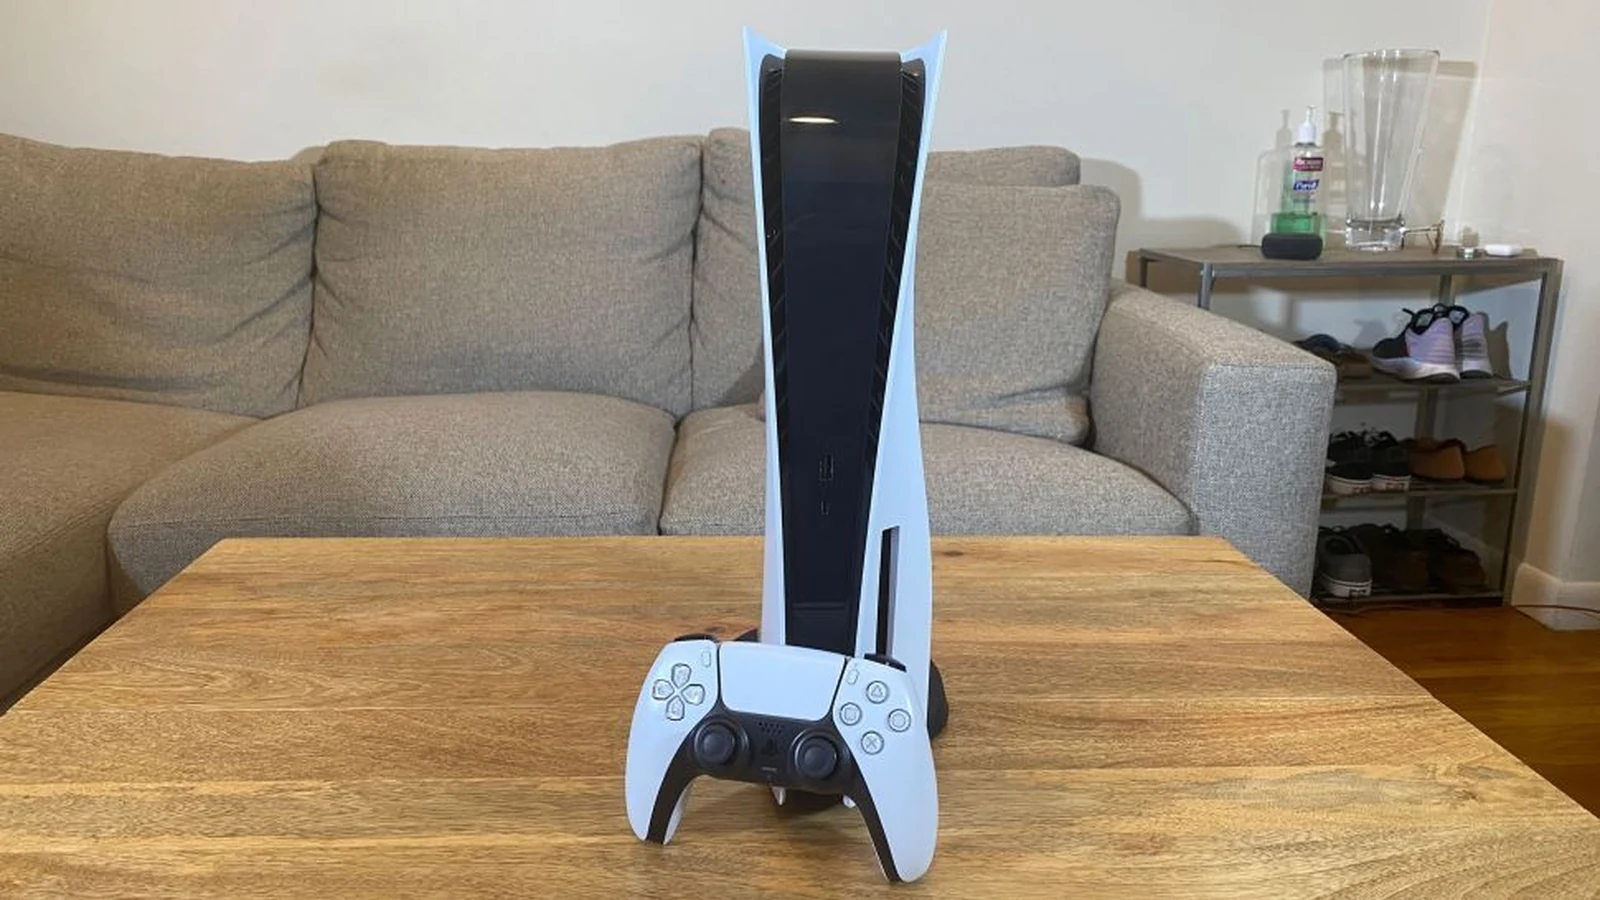
A developer has released a significant fork of the PS5LM project, enabling jailbroken PlayStation 5 consoles to execute local AI large language models natively by leveraging the system's GPU and up to 11.4 GiB of RAM.
 Radwan AbdulhadiEditor and technology writer
Native Execution and GPU Offloading
The capabilities of jailbroken PlayStation 5 consoles have expanded into local artificial intelligence following a new software development. According to a project shared on <a href="https://www.reddit.com/r/LocalLLM/comments/1x4y61f/qwen_27b_at_20_toks_on_a_jailbroken_ps5_gpu_i/?solution=c3d3908e4d46c3ebc3d3908e4d46c3eb&js_challenge=1&jsc_token=2824be10929bdc604753c70a67a1c3312b5cc064082b51d1e87953636ef0ce31&jsc_orig_r=">u/AdIllustrious7246</a>, a developer has created a fork of PS5LM—a llama.cpp port designed to run AI large language models locally—that executes natively on the console.
Earlier community efforts, including an <a href="https://www.reddit.com/r/ps5homebrew/comments/1wvbjwn/unofficial_llamacpp_port_for_ps5_in_progress_run/?share_id=hDmQKbd2fHFAWZLn8EefG&utm_content=share_button&utm_medium=web3x&utm_name=web3xcss&utm_source=share&utm_term=1">unofficial port of llama.cpp on Reddit</a> published by GitHub user cobanov, operated primarily as a CPU payload. That initial approach injected the language model instructions directly alongside system services and the home screen, which restricted memory access to roughly 6.25 GiB to prevent the system user interface from freezing.
Unlocking the AMD GPU via Vulkan
While the initial CPU payload method succeeded in bringing offline AI chat capabilities to the console, it lacked the ability to fully harness the hardware. The new fork overcomes this barrier by utilizing PS5_Vulkan, a port of the RADV graphics driver that routes instructions directly to the PlayStation 5 graphics processing unit.
Although the console features custom AMD hardware, its GPU is normally locked down and inaccessible in the manner of a standard desktop personal computer. The PS5_Vulkan project has opened up various homebrew applications by granting deeper access to the graphics hardware, enabling it to process neural networks far more efficiently than the CPU alone.
Performance Benchmarks and Model Sizes
By running natively and unloading computational demands onto the graphics processor, the updated implementation allows the console to utilize up to 11.4 GiB of system RAM. Previously, large 6.8 GiB language models frequently caused system freezes and crashes due to severe CPU bottlenecks.
With the hardware bottleneck mitigated, performance has scaled significantly across different model sizes. According to the developer's findings reported by <a href="https://www.tomshardware.com/video-games/playstation/jailbroken-ps5s-can-now-run-local-ai-models-at-over-100-tokens-per-second-fork-of-ps5lm-goes-native-and-accesses-gpu-and-more-ram">Tom's Hardware</a>, smaller models such as Llama 3.2 3B achieve generation speeds of 124 tokens per second, while Gemma 4 E4B reaches 61 tokens per second.
Furthermore, much larger architectures can now be executed. The system can run the Qwen3.8-27B parameter model at a rate of 20 tokens per second, demonstrating substantial processing capacity for local artificial intelligence workloads.
Dashboard Integration and Remote Access
In addition to native execution and improved token generation speeds, the updated application incorporates a dedicated dashboard interface. This display provides real-time telemetry, including live token generation rates, central processing unit and graphics processing unit utilization, power draw statistics, internal temperatures, and memory distribution between the model and the KV cache.
The implementation also features compatibility with llama.cpp's built-in web user interface. This addition allows external devices on the same local network to connect via a web browser and chat remotely with the artificial intelligence models hosted on the console.
Community Response and Context
The homebrew development has drawn attention from technology enthusiasts, with some drawing comparisons to the widespread graphics card shortages seen during previous cryptocurrency mining booms. However, hardware analysts note that a repeat of a crypto-style crisis is unlikely from this development.
The market is already experiencing hardware supply pressures driven by large-scale artificial intelligence data centers, and the console hardware does not possess the extreme memory bandwidth or processing specifications of high-end enterprise accelerators. Nonetheless, the achievement highlights the growing community interest in repurposing consumer gaming hardware for local artificial intelligence applications.
Sources
- Tom's HardwareJailbroken PS5s can now run local AI models at over 100+ tokens per second
Continue chronologically
Related stories
How to Clean Your PlayStation 5 Without Causing Damage
Learn how to safely clean your PlayStation 5 to remove dust, improve airflow, and keep your console running at its best without voiding your warranty.
Understanding the PlayStation 5 Game Library Padlock Symbol
Discover why a padlock icon appears on your PlayStation 5 game library and learn step-by-step methods to restore game access and licenses.
Jailbroken PS5s Can Now Run Steam PC Games Locally
Jailbroken PlayStation 5 consoles can now run Steam PC games using a newly adapted launcher that creates individual home screen tiles.
PS5 Hack Adds Native PS2 Disc Support and 4K Upscaling
A new homebrew project brings native PlayStation 2 disc support, 4K upscaling, and advanced features to jailbroken PlayStation 5 consoles.