Meta Uses Idle AI Inference to Enhance Ads Recommendations
Meta details a system designed to turn fragmented pockets of idle inference capacity into improved ads recommendations at scale.
 Radwan AbdulhadiEditor and technology writer
The Inference Capacity Paradox
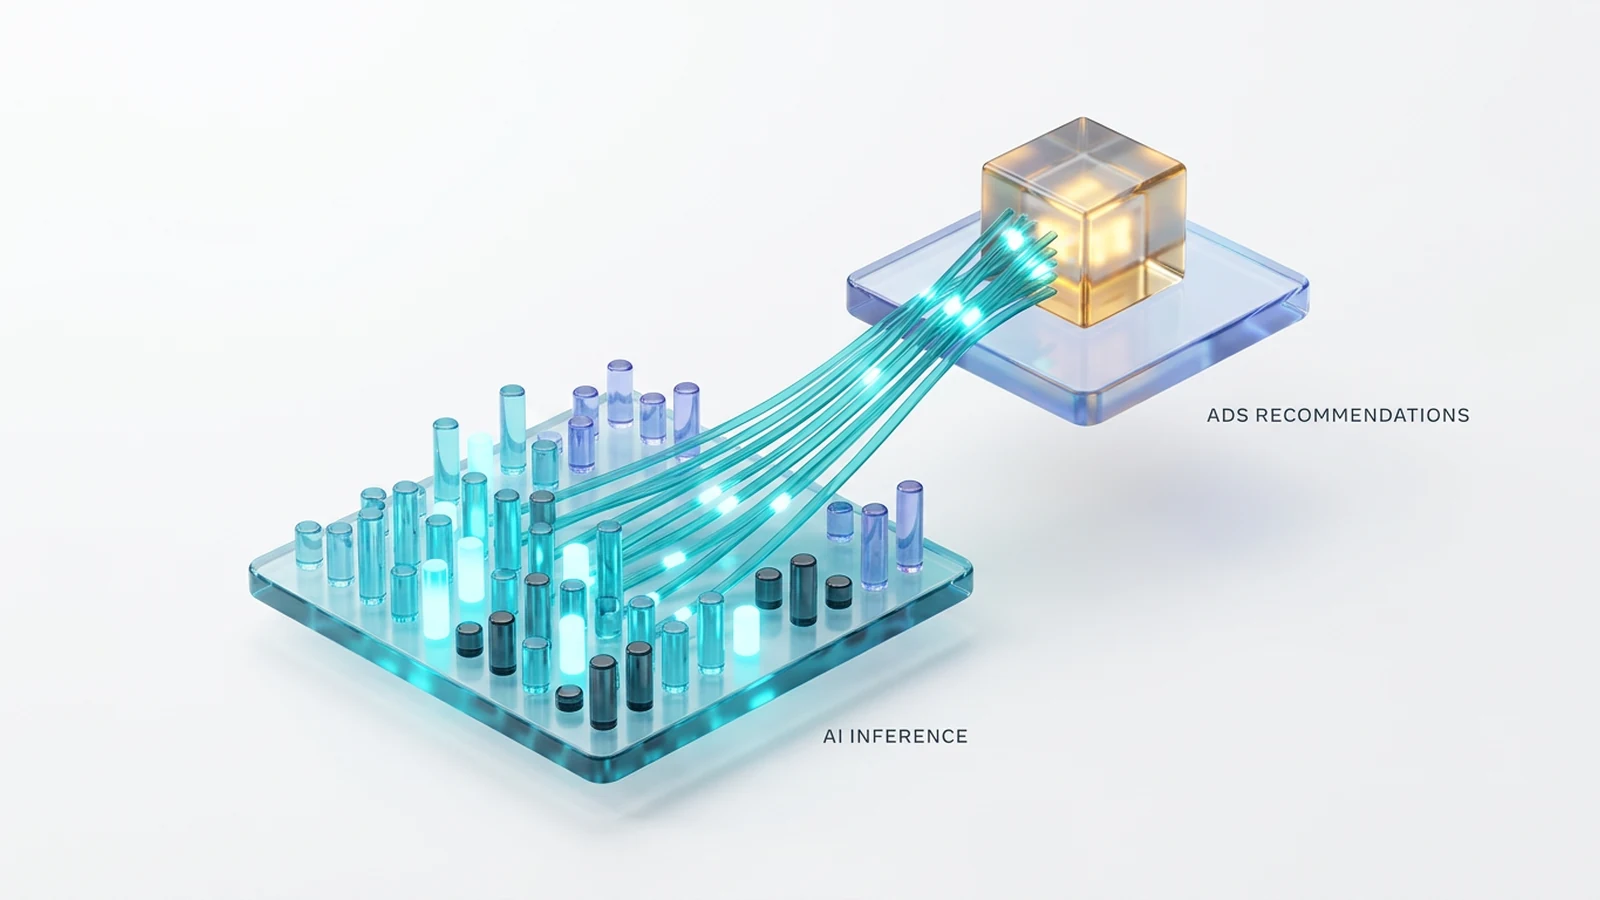
Inference fleets must maintain sufficient capacity to meet demand under strict latency and reliability targets, but demand and capacity rarely align perfectly. According to [Meta Engineering](https://engineering.fb.com/2026/10/12/ml-applications/turning-opportunistic-ai-inference-capacity-into-better-ads-recommendations/), capacity can remain idle in parts of a fleet even when the fleet is constrained overall due to regional resource-ratio mismatches, accelerator-type mismatches, and demand variations. Further details are available from Meta Engineering in the original source material.
Peak-provisioning and demand-variation mismatch further complicate resource usage. Because inference fleets must be provisioned for peak demand, capacity needed during peak periods often remains temporarily idle during lower-demand windows. Furthermore, model development schedules and supply-chain timelines for delivery rarely match up precisely, leaving temporary gaps.
From Fragmented Pockets to a Shared Pool
To address these challenges, engineers built a system that aggregates local idle pockets into a shared opportunistic capacity pool. This approach turns otherwise unused infrastructure into better ads recommendations, helping people see more relevant ads and improving advertiser outcomes without requiring additional capacity orders.
However, consuming volatile and preemptible capacity safely presents unique engineering challenges. The system must adapt workloads as supply changes without overloading dedicated capacity that serves baseline operations. Physical and logical isolation protects baseline reservations, while value-aware load shedding allows graceful degradation when capacity is reclaimed.
Rank More Ads (RMA)
The architecture relies on two complementary elasticity levers to consume opportunistic capacity. The first lever, Rank More Ads (RMA), adjusts the number of candidates evaluated by the ranking stages. When opportunistic capacity is available, evaluating more candidates increases the likelihood of finding relevant ads for users.
Because additional candidates must pass through CPU-heavy upstream operations such as feature processing and retrieval, in addition to accelerator-heavy inference, RMA generally requires a surplus of both CPU and accelerator resources.
Serve Better Models (SBM)
The second lever, Serve Better Models (SBM), changes the share of requests routed to more powerful, complex models as accelerator capacity changes. SBM keeps the number of ads entering the ranking stages constant, maintaining relatively stable upstream CPU demand.
This design allows SBM to consume accelerator-only surplus that RMA cannot utilize. Additionally, the SBM model-router component uses request-value signals to prioritize requests that stand to benefit most from enhanced model complexity.
System Scale and Operation
Operating the system at Meta's scale requires separate feedback loops to control RMA candidate volume and SBM model coverage. These mechanisms allow optional workloads to dynamically expand and contract in response to available supply while maintaining strict reliability and latency targets across the global fleet.
Sources
- Meta EngineeringTurning Opportunistic AI Inference Capacity Into Better Ads Recommendations
Continue chronologically
Related entity coverage
Related stories
Meta Introduces F3 Lightning to Scale Ads ML Features
Meta details F3 Lightning, a new infrastructure layer that accelerates ads machine learning features to production without increasing costs.
Meta Transforms Ads Recommendation with GenRecs Tokenization
Meta introduces GenRecs Tokenization, a foundational data representation leveraging stable semantic vocabularies to power generative ad recommendations.
Meta Engineers Detail Thin Orchestrator AI Agent Architecture
Meta details a thin orchestrator AI agent architecture that improves efficiency and reliability by giving central routers less domain work.
Meta Releases Muse Spark Open Multimodal MoE Model
Meta has introduced Muse Spark Open, an open-weight frontier multimodal mixture-of-experts model featuring 816 billion parameters.