Meta Transforms Ads Recommendation with GenRecs Tokenization
Meta is shifting its ads recommendation strategy away from scoring every individual ad candidate by introducing GenRecs Tokenization to jointly reason about ad content and user preferences.
 Radwan AbdulhadiEditor and technology writer
A Paradigm Shift in Recommendation Systems
Traditional ad recommendation systems have relied heavily on scoring every single ad candidate independently. However, Meta is transitioning toward reasoning about ad content and user preferences simultaneously using Large Language Model architectures. By leveraging pre-trained world knowledge, the underlying systems can better understand what an ad represents rather than merely matching past click patterns.
This advanced capability forms the core of <a href="https://engineering.fb.com/2026/10/19/ml-applications/genrecs-tokenization-transforming-ads-recommendation-at-meta-with-stable-model-vocabulary/">Meta Engineering</a> initiatives designed to improve ad matching precision and deliver compounding performance gains for advertisers across various digital surfaces.
How GenRecs Tokenization Works
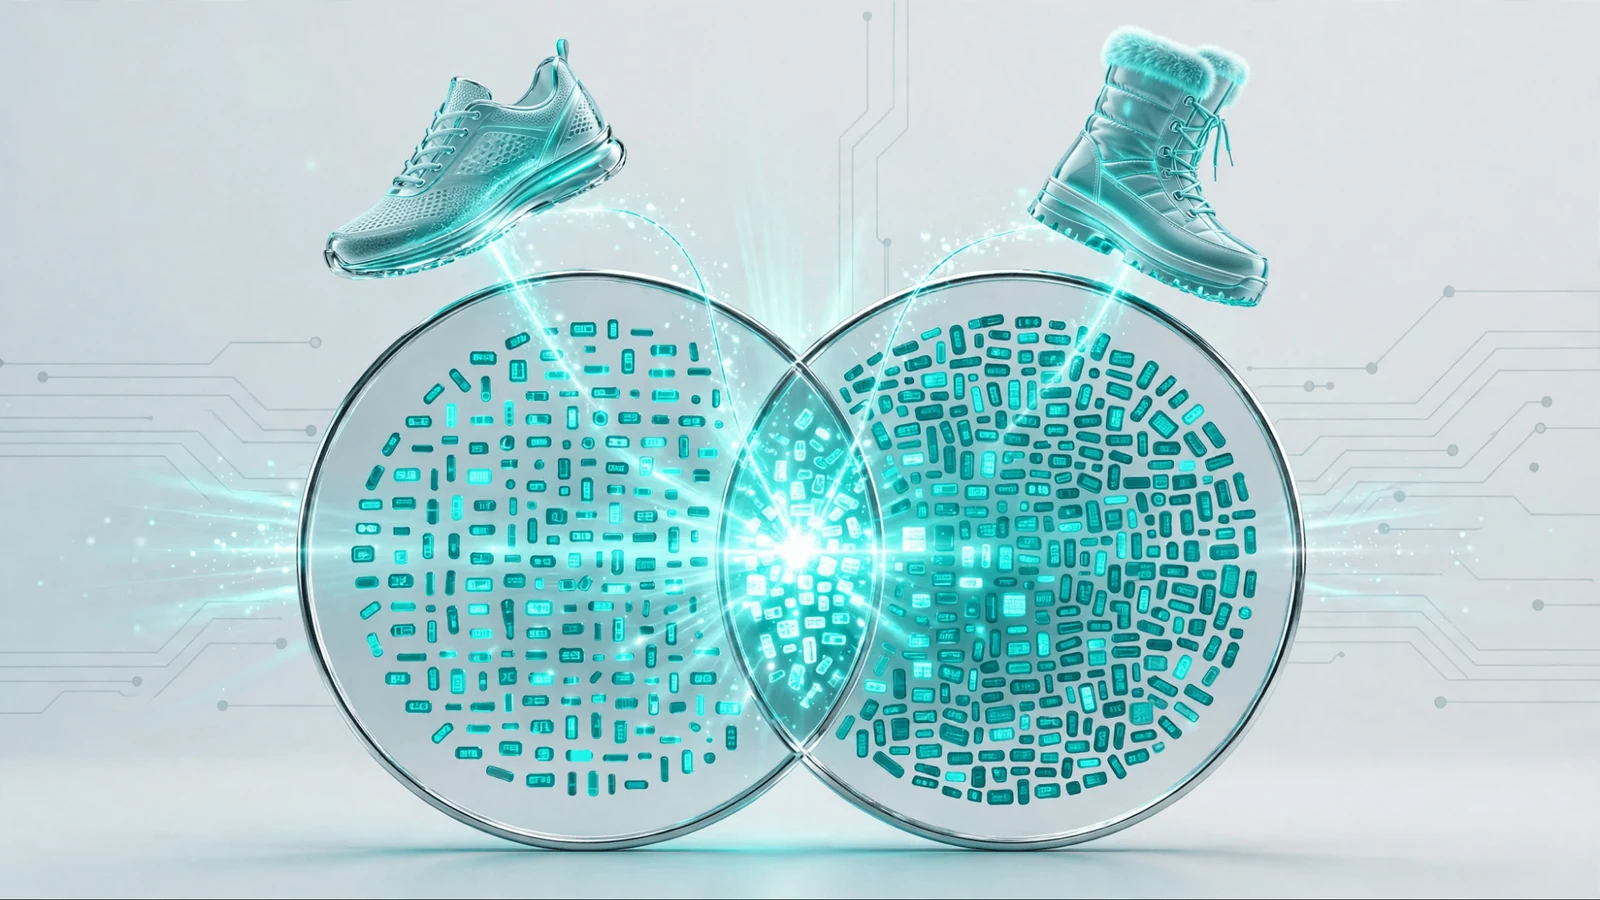
At the center of this technological shift is GenRecs Tokenization, which serves as the foundational data representation framework. Instead of maintaining a dedicated, isolated ID for every concept or item in the world, the architecture uses language models to compose a compact vocabulary of semantic tokens that represent any given item, such as ads, products, services, or pages.
Pre-trained multimodal models first read each item, including its accompanying text and images, and encode them into an embedding space that carries built-in world knowledge. The tokenizer subsequently combines that content signal with historical engagement representations, quantizing the output into a short sequence of discrete tokens.
The Three-Stage Tokenization Pipeline
Maximizing ad recommendation quality requires a structured sequence of operations. The core architecture relies on a specialized three-stage pipeline to process items effectively.
First, the system encodes each item into a semantic embedding space. Second, it decomposes that embedding into independent subspaces. Third, it quantizes the data by mapping each subspace to a specific entry in a codebook, utilizing prefix n-grams that combine learned encoders, residual decomposition, vector codebooks, and token parameterization.
Addressing Cold-Start Challenges and Tail Ads
One of the major advantages of semantic tokenization is its ability to handle newly launched products and niche advertisements that lack extensive historical engagement data. Because tokens describe the fundamental nature of an item, a brand-new product can instantly inherit knowledge from related categories.
For instance, when a sportswear brand introduces a new line of trail shoes, the model connects the item to previous seasons' products through shared token patterns. This allows the system to overcome cold-start limitations and facilitate cross-campaign transfer for advertisers.
Production Performance and Integration
When integrated with other core architectural components, GenRecs Tokenization demonstrates measurable production improvements. By working alongside <a href="https://engineering.fb.com/2025/11/10/ml-applications/metas-generative-ads-model-gem-the-central-brain-accelerating-ads-recommendation-ai-innovation/">Meta’s Generative Ads Model (GEM)</a> and <a href="https://engineering.fb.com/2026/03/31/ml-applications/meta-adaptive-ranking-model-bending-the-inference-scaling-curve-to-serve-llm-scale-models-for-ads/">Meta’s Adaptive Ranking Model</a>, internal data measured in February 2026 confirmed a +0.35% lift in conversions across surfaces.
This optimization creates a self-reinforcing flywheel effect. Improved tail ad prediction quality refines the underlying training data, which subsequently elevates prediction accuracy for all advertisements managed by the system.
Sources
- Meta EngineeringGenRecs Tokenization: Transforming Ads Recommendation at Meta with Stable Model Vocabulary
Continue chronologically
Related entity coverage
Related stories
Meta Introduces F3 Lightning to Scale Ads ML Features
Meta details F3 Lightning, a new infrastructure layer that accelerates ads machine learning features to production without increasing costs.
Meta Engineers Detail Thin Orchestrator AI Agent Architecture
Meta details a thin orchestrator AI agent architecture that improves efficiency and reliability by giving central routers less domain work.
Meta Releases Muse Spark Open Multimodal MoE Model
Meta has introduced Muse Spark Open, an open-weight frontier multimodal mixture-of-experts model featuring 816 billion parameters.
Meta’s Muse Spark Open Available in SageMaker JumpStart
Meta’s coding-optimized open-weight model, Muse Spark Open, is now accessible in Amazon SageMaker JumpStart for deployment on SageMaker AI.