
NarrateAI Brings LLM Quality Assurance to Amazon Bedrock
The second installment of the NarrateAI series details the engineering practices used to achieve production-ready quality assurance and high numerical accuracy for executive business reviews.
 Radwan AbdulhadiEditor and technology writer
Introduction to NarrateAI Quality Assurance
Executives relying on conversational agentic AI assistants during live business reviews require absolute speed and precision. In production environments, gaps such as hallucinated metrics, API throttling, validation latency, and subjective language can cause immediate professional challenges. A capable large language model alone cannot resolve these issues, prompting the development of production-ready quality assurance mechanisms.
Detailed on the AWS Machine Learning Blog, NarrateAI transforms business intelligence for over 4,000 AWS executive leaders. The system operates via a two-layer architecture built on Amazon Bedrock AgentCore, which allows teams to build, connect, and optimize agents at scale using any framework or model.
The Five Quality Assurance Techniques
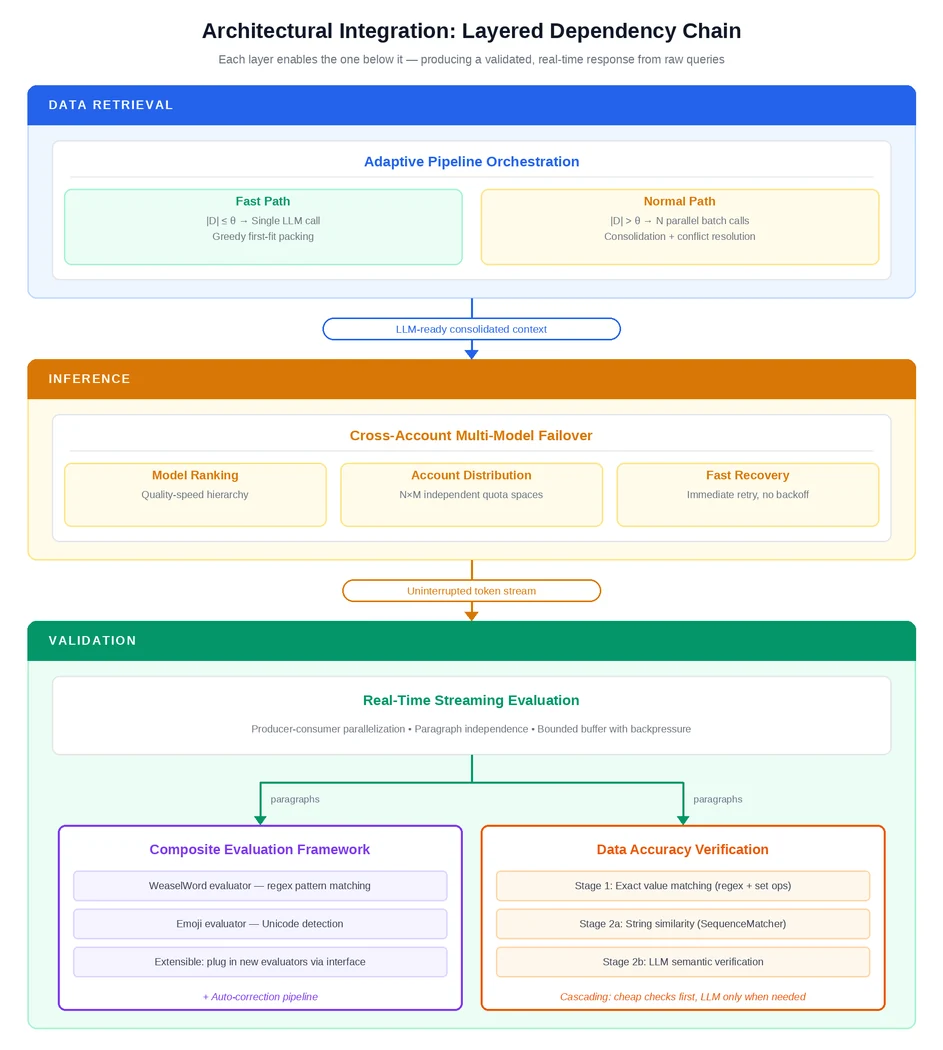
To bridge the gap between raw LLM outputs and executive-ready reliability, NarrateAI integrates five specialized techniques deployed on Amazon Bedrock. These methods work together as a coordinated system to address distinct failure modes, ranging from data retrieval to final response delivery.
The five mechanisms include adaptive pipeline orchestration, cross-account multi-model failover, real-time streaming evaluation, a composite evaluation framework, and data accuracy verification. Together, these layers form a structured dependency chain that turns raw queries into validated real-time responses while reaching approximately 99% numerical accuracy.
Adaptive Pipeline Orchestration
Query complexity and data volumes vary significantly across enterprise knowledge documents. While focused queries might only require a few document sections, comprehensive requests can demand synthesis across hundreds of sources. To handle this heterogeneity without sacrificing response time, adaptive pipeline orchestration routes each query based on its total aggregated section volume.
The pipeline processes queries through up to three distinct phases. First, Mode-Aware Consolidation packs retrieved sections and determines the optimal route using a character-count threshold. Smaller data volumes take a fast path via a single LLM invocation, while larger volumes use a normal path with parallel batch processing. Finally, conditional consolidation merges parallel results when necessary.
Failover and Real-Time Evaluation
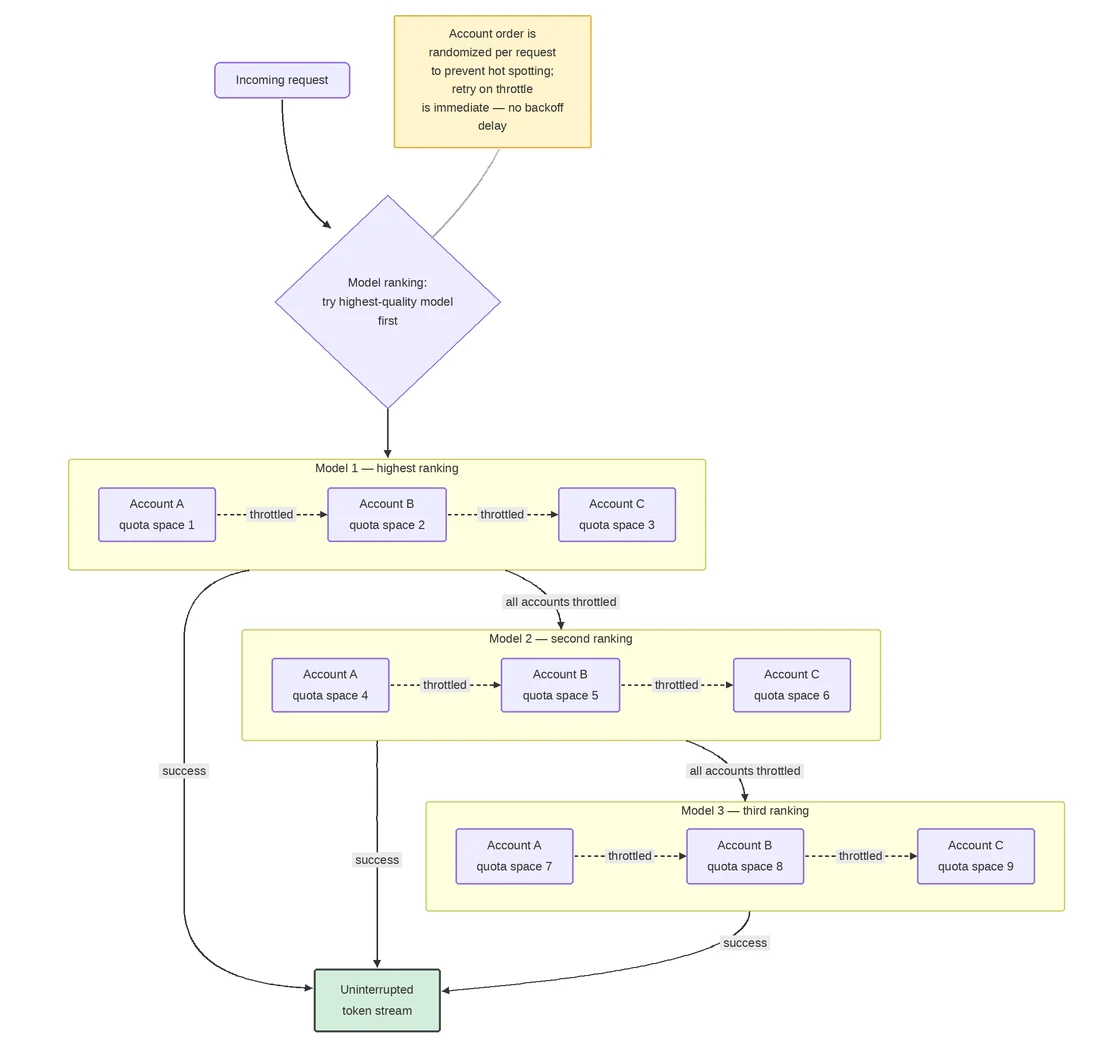
During periods of heavy concurrent usage, enterprise applications frequently encounter API limits and capacity bottlenecks. Cross-account multi-model failover addresses this by expanding available inference capacity across independent model-account quota spaces, effectively minimizing user-visible throttling during executive sessions.
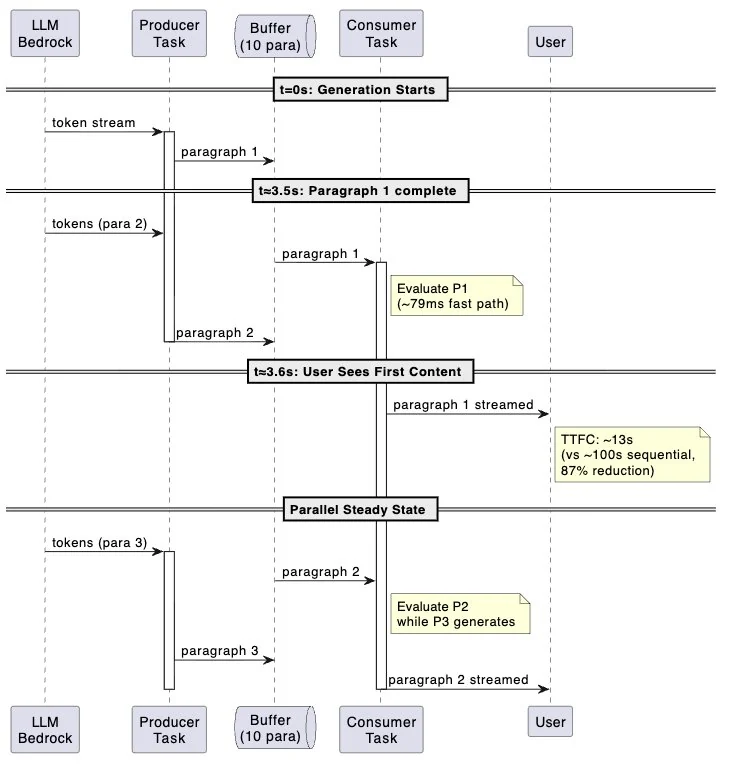
Additionally, real-time streaming evaluation validates each paragraph the moment it is generated, overlapping quality checks directly with the streaming output. The composite evaluation framework then runs multiple independent evaluators in parallel against each paragraph to maintain strict professional standards.
Data Accuracy Verification
Catching numerical hallucinations requires rigorous checks before the information reaches leadership. NarrateAI applies a data accuracy verification mechanism through a two-stage cascade. The system starts with cost-effective exact matching and escalates to semantic verification only when necessary.
These engineering practices build upon previous deployments outlined in the previous post, providing a robust framework for enterprise-grade conversational AI. By combining multiple verification strategies, the architecture ensures that responses delivered during live reviews remain trustworthy and precise.
Sources
- AWS Machine Learning BlogNarrateAI: production-ready LLM quality assurance on Amazon Bedrock