NVIDIA Launches Nemotron 3.5 Transcribe and Granary v2
NVIDIA has released Nemotron 3.5 Transcribe alongside the Granary v2 data pipeline, combining multilingual transcription, translation, speaker attribution, and audio question-answering into a single open-weight model.
 Radwan AbdulhadiEditor and technology writer
Unified Multilingual Capabilities and Architecture
NVIDIA has introduced Nemotron 3.5 Transcribe, an open-weight, promptable speech model that merges transcription, speaker attribution (diarization), translation, and audio question-answering into a single unified checkpoint. According to details shared on the Hugging Face Blog, the model can transcribe speech in 40 languages, translate 31 of them to or from English, and perform speaker attribution across 13 languages. It is designed to process recordings up to an hour long and can label up to eight distinct speakers.
Under the hood, Transcribe pairs a speech encoder with a hybrid Mamba-Transformer mixture-of-experts language model. This architecture enables the system to run efficiently on a single NVIDIA GPU—ranging from DGX Spark to Blackwell data-center systems—utilizing approximately 4 billion active parameters out of a total 30 billion per token. Developers can leverage natural language prompts to guide output formatting, adapt recognition to specific domain vocabulary, and choose where their audio is processed.
Strong Leaderboard Performance and Benchmarks
Nemotron 3.5 Transcribe has secured top placements across multiple prominent evaluations for speech recognition and speaker diarization. On the Hugging Face Open ASR Leaderboard for English, it ranks first among open-weight models with a 5.33% average word error rate (WER). It also achieves the lowest mean WER in the leaderboard's multilingual and long-form evaluation tracks.
Furthermore, the model sits on Artificial Analysis’s accuracy-active-parameter frontier, tying for first place among open-weight models with a 2.8% AA-WER index score. In speaker attribution benchmarks, Transcribe posts the lowest error rate on David AI’s 21-language diarization leaderboard and secures the top rank in VoiceArena's 14-system comparison.
Granary v2 Data Pipeline and Fine-Tuning Recipes
Alongside the model release, NVIDIA has introduced Granary v2, offering a multilingual data pipeline and reusable curation tools. Combined with NeMo Speech fine-tuning tools, developers can extend prompt-level control directly into the training phase, adapting the model to specialized vocabulary and distinct application environments.
In a medical case study highlighted by the project documentation, fine-tuning cut the word error rate on held-out speakers by 45.8% relative to the best baseline prompt. This allows healthcare providers and enterprise users to better preserve standard medical spelling, handle complex domain jargon, and manage unconventional formatting requirements safely.
Real-World Applications and Prompting Flexibility
The promptable design of Nemotron 3.5 Transcribe allows a single checkpoint to handle diverse tasks based on simple natural language instructions. Users can direct the system to transcribe a recording while labeling every speaker, translate dialogue, or answer audio questions using the model's recommended reasoning presets.
Real-world implementations are already underway across various sectors. For instance, Agora integrated word-level timestamps from Nemotron 3.5 Transcribe into a classroom demonstration on their real-time voice and video platform. This setup generates structured transcripts alongside session replays, giving students clear visibility into what was said and when.
Sources
- Hugging Face BlogNVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Continue chronologically
Related entity coverage
Related stories
NVIDIA Launches Nemotron 3 Diarization Open-Weight Model
NVIDIA introduces Nemotron 3 Diarization, a 100M-parameter open-weight model topping VoiceArena's leaderboard for real-time multi-speaker AI.
NVIDIA Fine-Tunes Nemotron for Gold-Level IMO and IOI Results
NVIDIA demonstrates how fine-tuning the Nemotron model family using SFT, RL, and inference loops achieved gold-medal levels at IMO 2026 and IOI 2026.
NVIDIA and AI4Bharat Launch Indic Pretraining Corpus
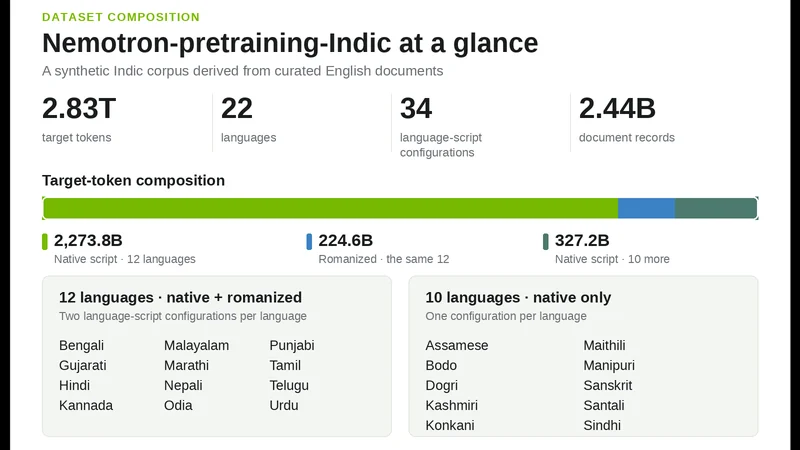
NVIDIA and IIT Madras lab AI4Bharat introduce Nemotron-pretraining-Indic-v1, featuring 2.8 trillion tokens and an open data generation pipeline.
NVIDIA Expands Nemotron 3.5 with New Retrieval Models
NVIDIA expands its Nemotron collection with open models for embedding, reranking, and document parsing to enhance enterprise agent workflows.