Nvidia Releases New Open Voice Transcription Model
Nvidia has expanded its portfolio of artificial intelligence audio tools with the release of a new open-weight transcription model designed to handle business meetings and medical records.
 Radwan AbdulhadiEditor and technology writer
Introduction to Nemotron 3.5 Transcribe
Nvidia has released a free, open-weight model that transcribes audio in up to 40 languages, alongside version 2 of Granary, its open source speech dataset. According to reporting by TechCrunch, the model expands the company's offerings in the artificial intelligence voice sector.
The newly introduced Nemotron 3.5 Transcribe is designed to handle audio files of up to an hour in length and can translate 31 languages to and from English. Furthermore, the system possesses the capability to distinguish up to eight individual speakers within a given recording.
Target Use Cases and Performance Benchmarks
The tools are specifically aimed at software developers building applications for corporate meetings and medical transcription, which represent two of the most established enterprise use cases for artificial intelligence. Nvidia states that developers can utilize the model, the updated Granary dataset, and tools like its NeMo Speech model to customize applications so they can recognize specific industry jargon across different languages.
Nvidia claims that its model surpasses competing systems on several industry benchmarks, including evaluations tracked on Hugging Face's Open ASR Leaderboard. Developers interested in exploring the technical parameters can access the system directly through Hugging Face.
Technical Specifications and Limitations
Despite its large scale of 30 billion parameters, Nvidia promises that Nemotron 3.5 Transcribe is optimized to run efficiently on a single hardware chip. Supported hardware ranges from the Jetson AGX Thor robotics controller and the DGX Spark chip powering new laptops, up to heavy-duty Blackwell datacenter chips.
The model joins a broader ecosystem of Nvidia open-weight voice technologies, which includes smaller offerings like the powerful Parakeet model. However, the system does feature a notable functional limitation: it is built strictly for recorded audio files and does not support live audio streaming.
Broader Industry Context in Voice AI
Nvidia’s introduction of its transcription model coincides with a particularly active period for artificial intelligence voice releases across the technology sector. Competitors have rolled out several major voice products recently, including Mistral, which shipped Voxtral 3, ElevenLabs, which launched Realtime for instant speech in voice agents, and Salesforce, which released its Launa-Omni voice model.
Sources
- TechCrunchVoice AI in vogue: Nvidia releases new open transcription model
Continue chronologically
Related entity coverage
Related stories
Mistral Large 4 Trails Some Chinese Open Models in Tests
Independent benchmarking ranks Mistral's new trillion-parameter Large 4 model as a top non-US and non-China AI model, though it trails certain Chinese open alternatives.
Nvidia Launches Open Models for Enterprise and PC Agents
Nvidia has launched new open-weight models, including the Super VL for enterprise data centers and Bolt models for local AI PCs and workstations.
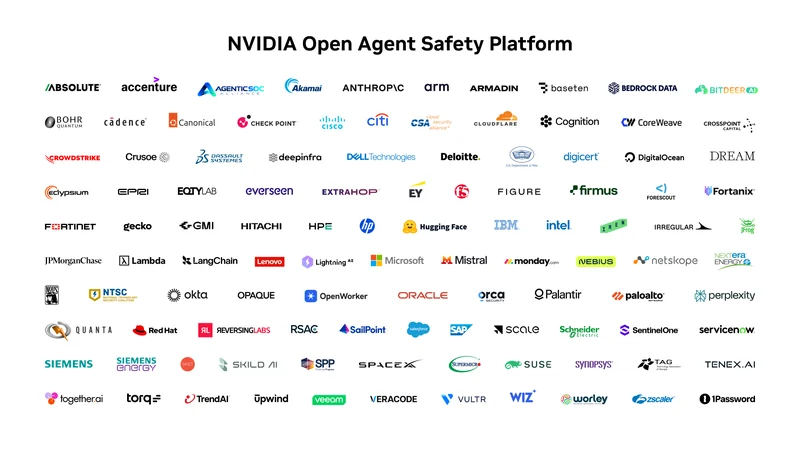
Nvidia Launches Open Agent Safety Platform to Restrain AI
Nvidia has launched the Open Agent Safety Platform, combining OpenShell sandboxing and BlueField hardware to quarantine rogue AI agents.
Nvidia Discusses $2,000-per-GPU Annual Software Fee
Nvidia is reportedly weighing an annual software licensing fee of around $2,000 per GPU to run enterprise AI agents on AI infrastructure.