OpenAI GPT Models Arrive on Amazon Bedrock in Canada
Amazon Bedrock brings OpenAI GPT models to Canadian AWS regions through cross-Region inference profiles, supporting multiple APIs and large context windows.
 Radwan AbdulhadiEditor and technology writer
Bringing OpenAI Models to Canadian AWS Regions
Canadian organizations building generative AI applications on Amazon Bedrock can now utilize advanced foundation models from OpenAI using cross-Region inference. As detailed in the AWS Machine Learning Blog, OpenAI GPT-5.6, GPT-6, and GPT-6.1 models are now accessible from the Canada (Central) and Canada West (Calgary) Regions. This capability allows local teams to integrate cutting-edge artificial intelligence while processing inferences within North America under specific data-residency controls.
Cross-Region inference acts as a capacity mechanism for applications experiencing demand spikes. When an application calls the Amazon Bedrock Runtime endpoint in a local source Region, Amazon Bedrock automatically routes the request to a supported destination Region for processing without requiring manual routing management in the application code.
Model Capabilities and Inference Profiles
The available OpenAI model lineup includes GPT-5.6 variants such as Sol, Terra, and Luna, alongside GPT-6 models Astra, Sol, and Luna, and GPT-6.1 Sol. These models accept text and image inputs, output text, and incorporate a 1-million-token context window along with reasoning mode and tool calling. Developers can review specific per-model Region availability by checking the model cards in the Amazon Bedrock User Guide.
Amazon Bedrock inference profiles serve as logical identifiers replacing raw model IDs. Two distinct profile types are offered in Canada: US geographic profiles prefixed with 'us.' which route requests to the Canadian source Region and US Regions for North American data processing, and global profiles prefixed with 'global.' which route requests to wider commercial AWS Regions where the model is deployed. Comprehensive details regarding supported endpoints can be found in the Cross-Region inference support documentation.
Prerequisites and IAM Permissions
Before invoking these models from a Canadian source Region, developers must ensure their AWS account has enabled either Canada (Central) or Canada West (Calgary). Furthermore, engineers need an IAM role or user equipped with appropriate permissions to invoke the chosen inference profiles. Quick exploratory setups can leverage the AWS managed policy AmazonBedrockLimitedAccess, whereas production workloads with strict compliance requirements should implement least-privilege custom policies.
Organizations enforcing service control policies can establish precise rules for multi-account environments. Administrators can consult the guide on how to set up cross-Region inference in multi-account environments to ensure that traffic flows smoothly through approved inference profile ARN condition keys while restricting unauthorized direct calls to unapproved regions.
API Integration and Invocation Paths
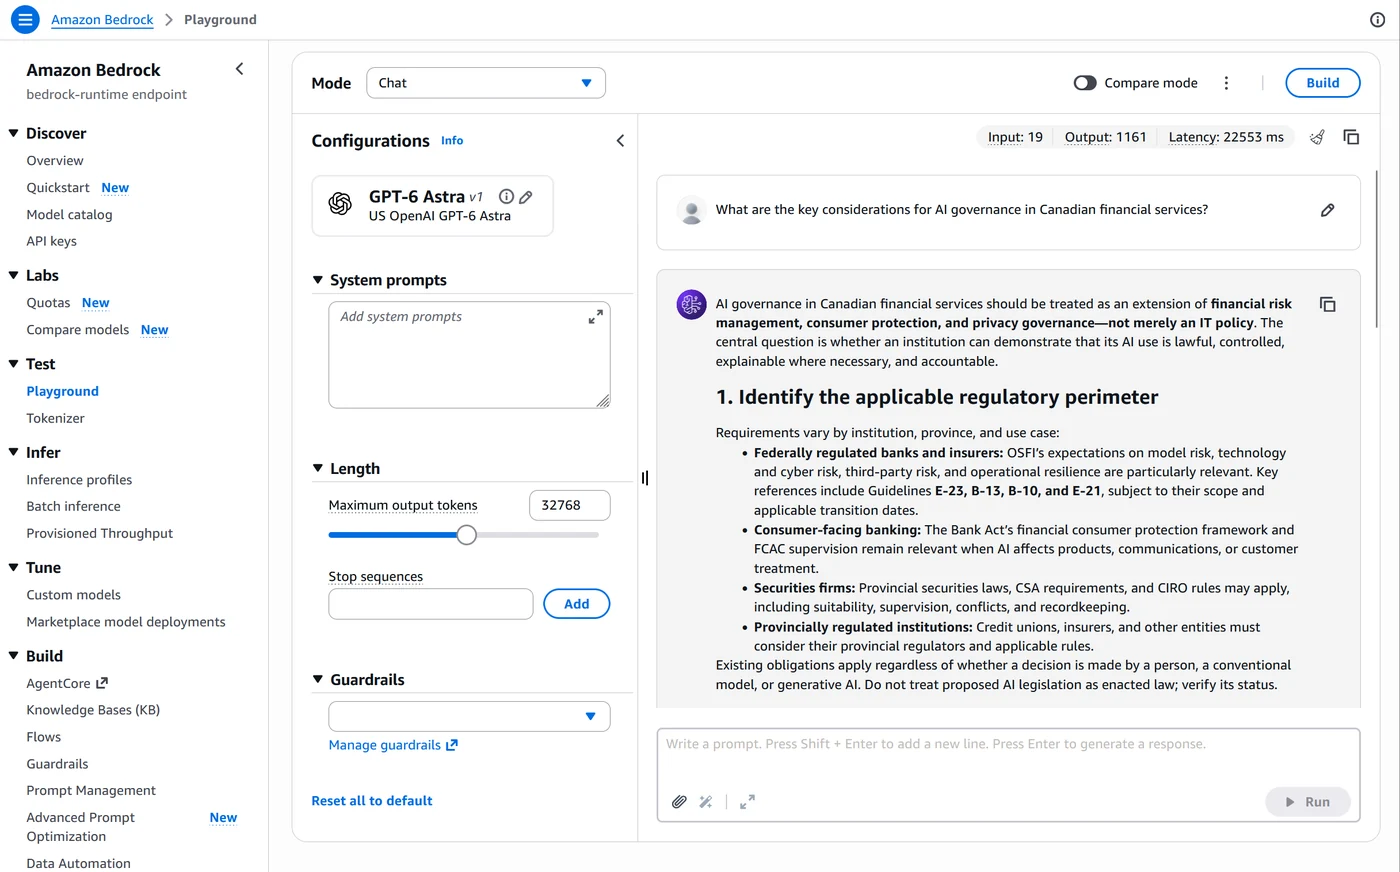
GPT-5.6, GPT-6, and GPT-6.1 support three primary access paths on the bedrock-runtime endpoint: the OpenAI Responses API, the OpenAI Chat Completions API, and the Amazon Bedrock Converse API. The OpenAI-compatible endpoints operate on the /openai/v1 paths and accept either AWS Signature Version 4 or an Amazon Bedrock API key for secure authentication.
Developers can utilize tools such as the Amazon Bedrock token generator for Python to dynamically create short-term API keys from active AWS credentials, removing the security risk of storing static keys. Applications already utilizing the standard OpenAI SDK can simply point their client at the Regional Amazon Bedrock Runtime endpoint and pass the specific cross-Region inference profile ID as the model parameter.
Pricing, Caching, and Ongoing Management
Pricing structures for utilizing OpenAI models via cross-Region inference on Amazon Bedrock follow standard AWS guidelines. Teams calculating expenses and projecting operational budgets can consult official Amazon Bedrock pricing pages for comprehensive rate breakdowns.
In addition to standard inference handling, the newly available models support advanced features such as prompt caching. Developers looking to optimize token efficiency and reduce latency can reference the prompt caching documentation for configuration instructions, while monitoring workload observability signals directly from their chosen Canadian source Region.
Sources
- AWS Machine Learning BlogAccess OpenAI GPT models on Amazon Bedrock from Canada with cross-Region inference
Continue chronologically
Related entity coverage
Related stories
OpenAI GPT Models Arrive on Amazon Bedrock in Asia
Amazon Bedrock brings OpenAI GPT-6 models to Thailand, Malaysia, Singapore, Indonesia, and Taiwan using global cross-Region inference.
AWS Recaps September 2026 AI Updates for Bedrock and Strands
Explore the September 2026 updates for Amazon Bedrock, AgentCore, and Strands, bringing broader model choice, automated syncing, and serverless agents.
GPT-6.1 Sol Now Available on Amazon Bedrock
GPT-6.1 Sol is now generally available on Amazon Bedrock, bringing near-Astra intelligence and advanced reasoning to everyday professional workflows.
Amazon Bedrock Prompt Caching for OpenAI Models
Discover how prompt caching patterns on Amazon Bedrock help AI agents cut input costs and reduce latency by eliminating redundant context processing.